A Survey of
AI for AI
From Long-Horizon Agents to Recursive Self-Improvement
Definitions, Reliable Horizons, and Open Problems
Tongji · SJTU · UC Berkeley · CASIA · NUS · NTU · Simple Agent Lab
PDF (original layout) ↓ RSIHub harness ↗ Blog ↗ DOI ↗ Cite ↗
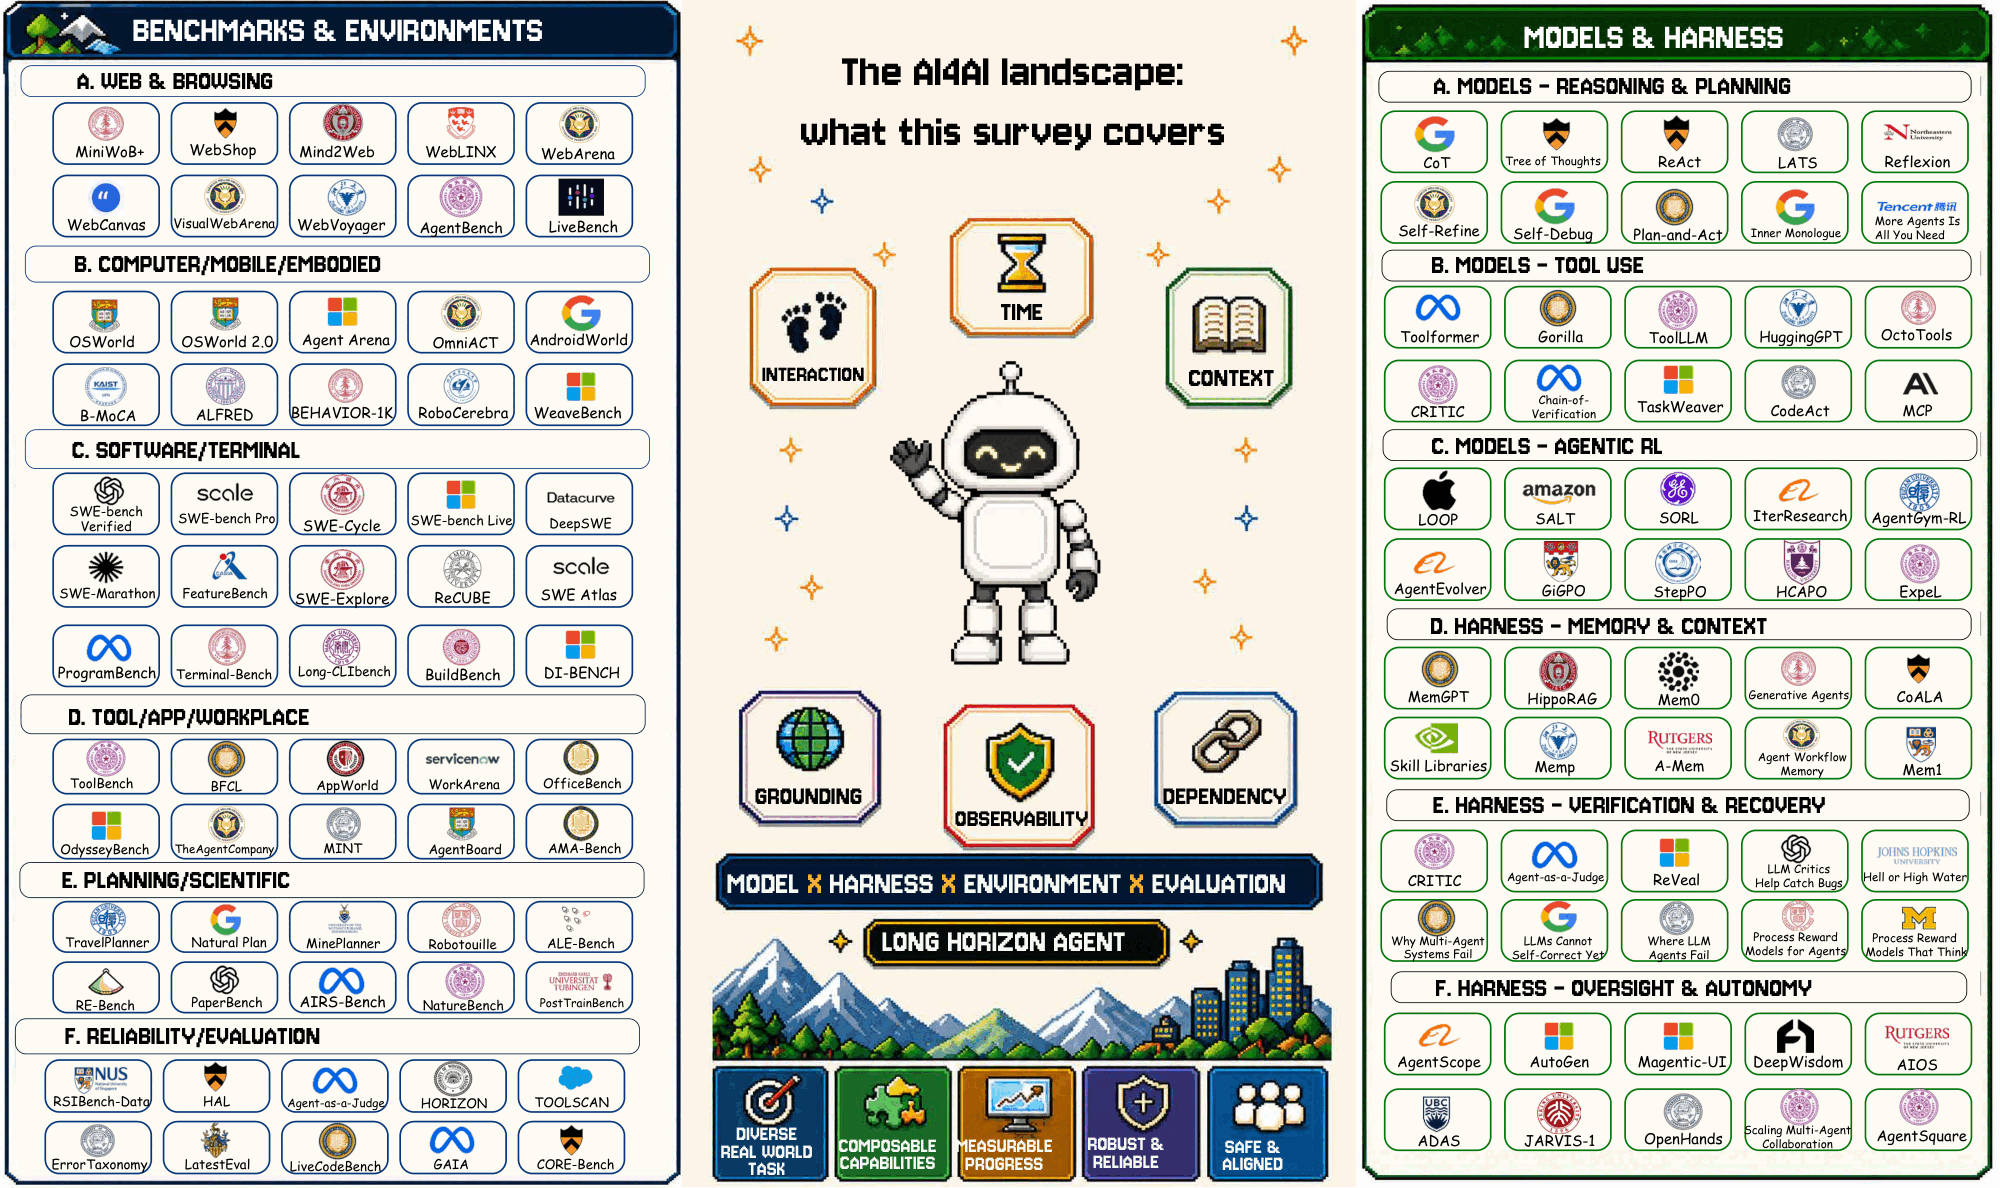
01 · THE RESEARCH ATLAS
See the field.
Connect the systems.
One visual map for the benchmarks that measure agents, the harnesses that guide them, and the model interventions that make them improve.
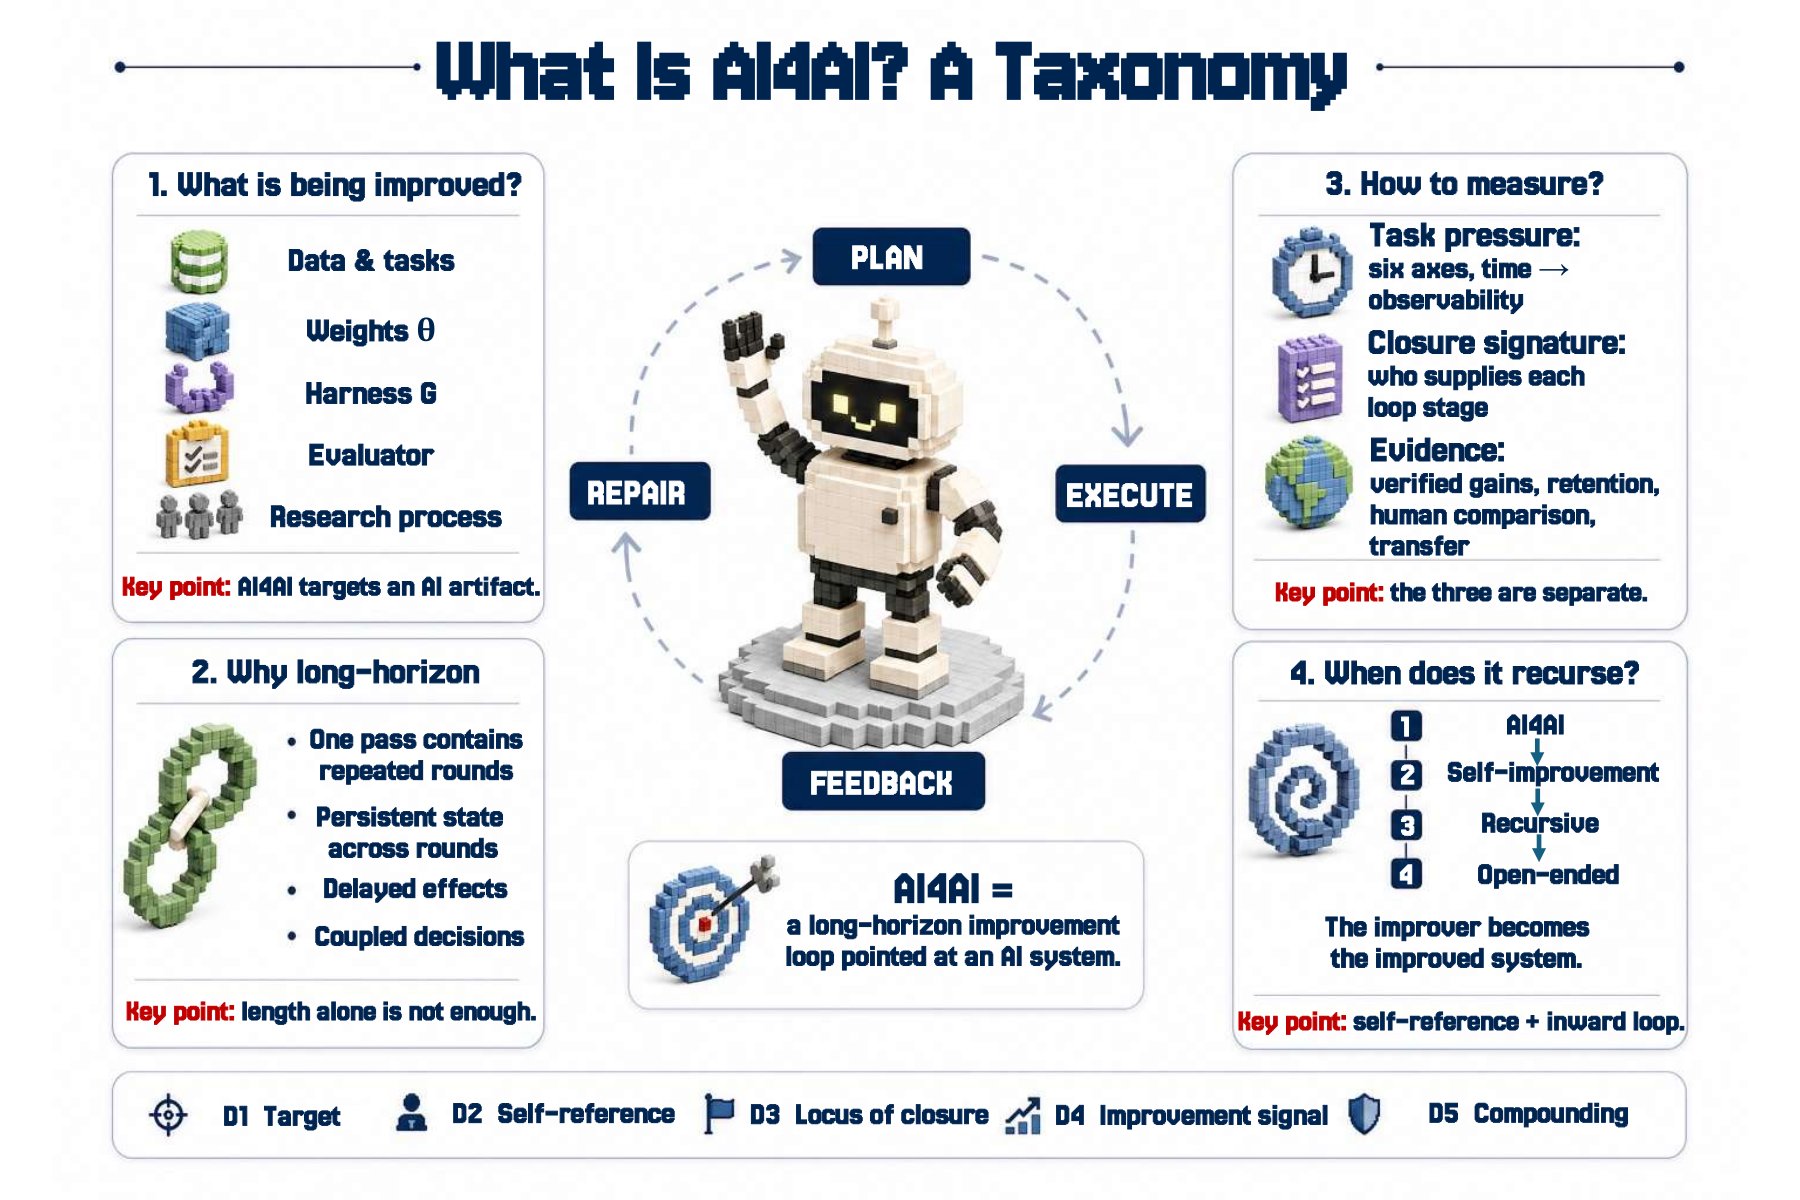
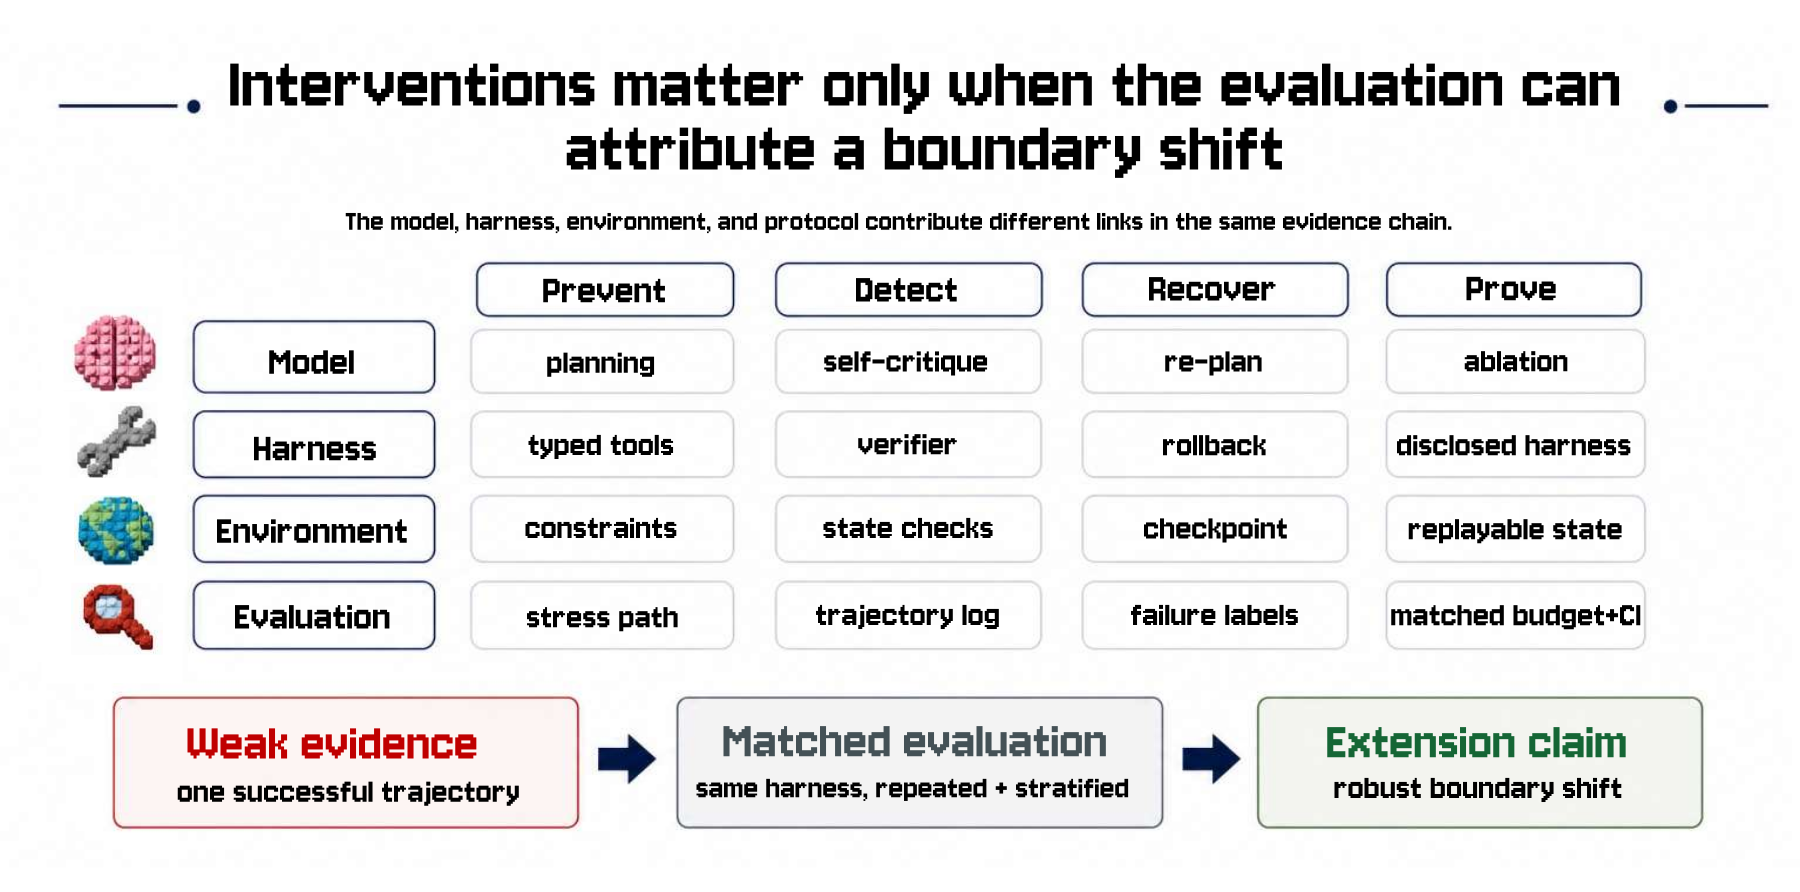
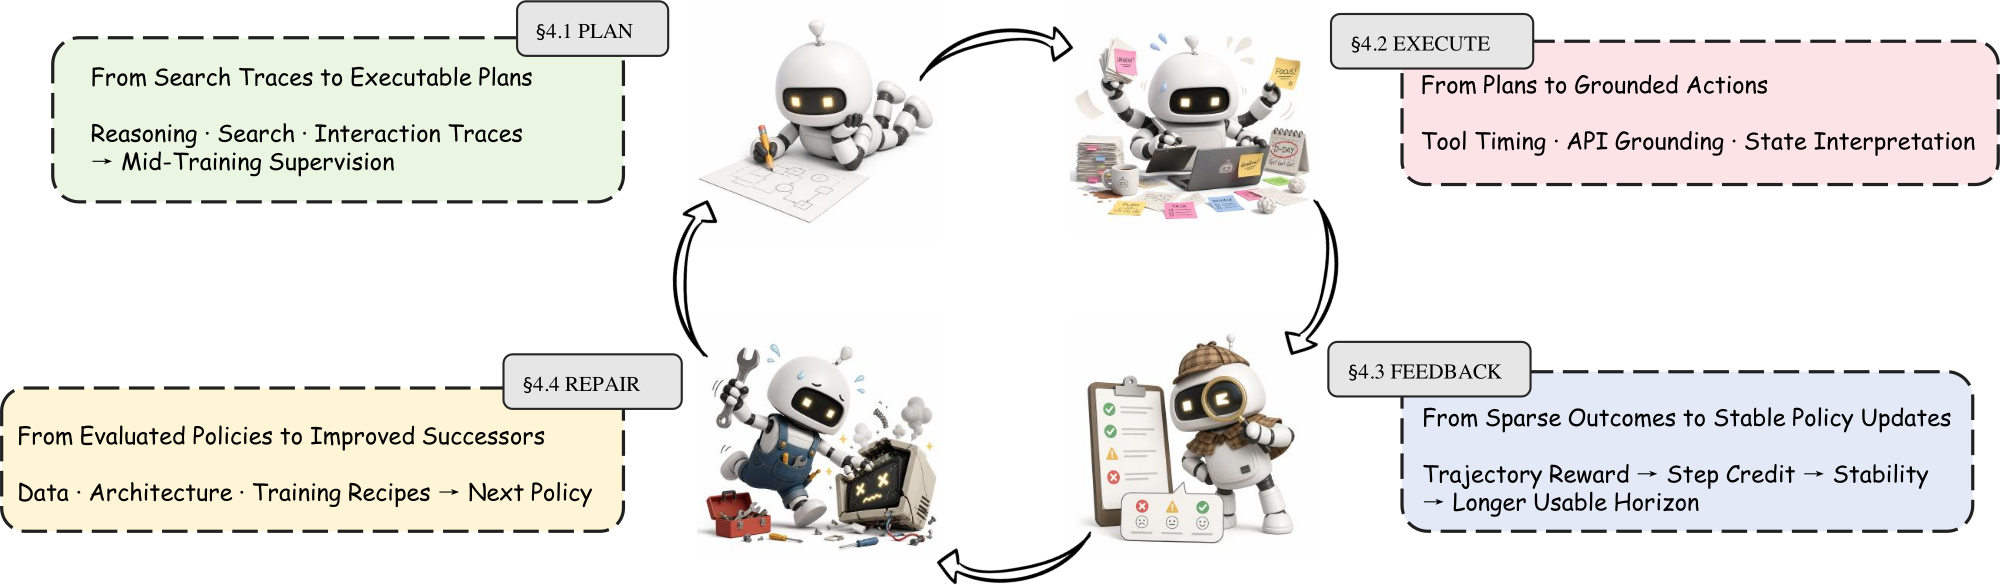
Every paper,
placed on the map.
The survey's complete taxonomy — from “What is AI4AI?” through evaluation, model design, and harness design, to the open problems — with each of the original survey’s 223 papers attached to the section that cites it.
Browse the catalog ↗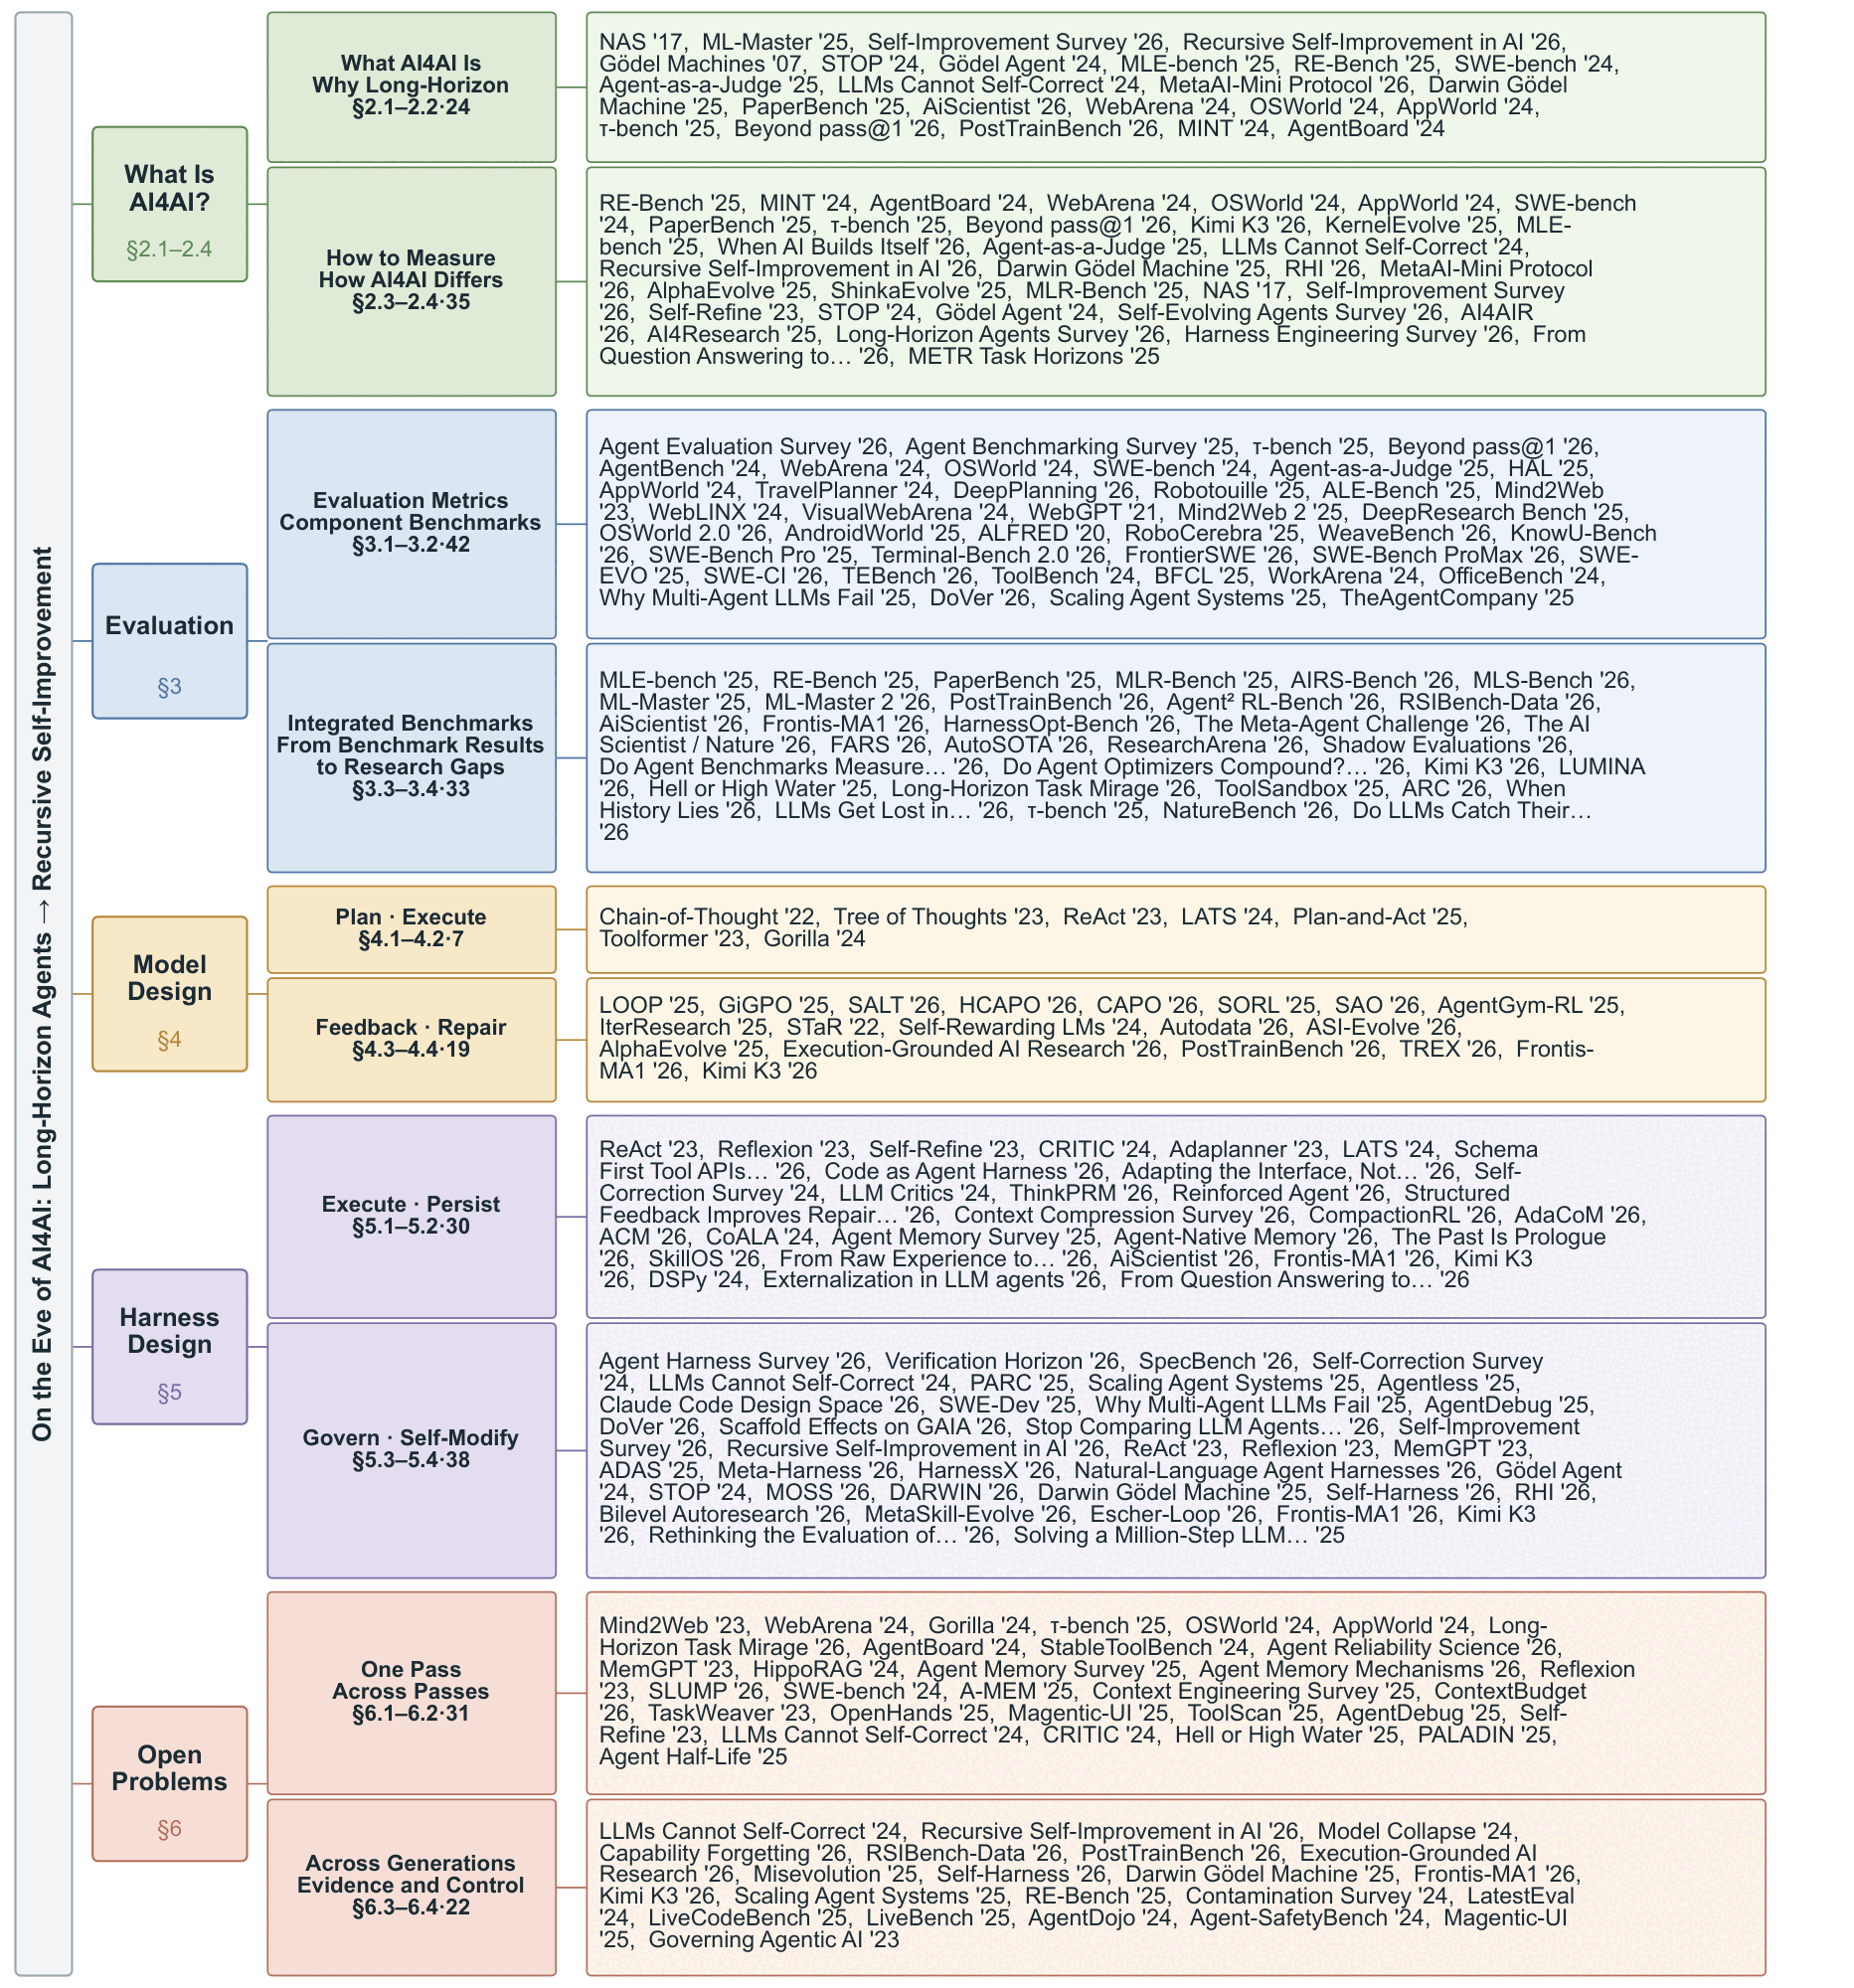
02 · LIVE COLLECTIONS
Curated for signal,
built for discovery.
Weekly intelligence
The month's highest-signal papers, releases, and research news—source-checked and reranked every Monday.
Open the signal feed ↗ 02Live rankings
Citation velocity, yearly leaders, and code popularity refreshed from scholarly APIs and GitHub.
See live rankings ↗ 03Evidence audit
Traceable evidence for stage ownership, generalization, robustness, horizon, and transfer claims.
Inspect the evidence ↗03 · REPRODUCIBLE BY DESIGN
Every claim has
a trail.
Discover, verify, classify, audit, and refresh. The catalog combines human research judgment with reproducible data and weekly automation.
Read the methodology →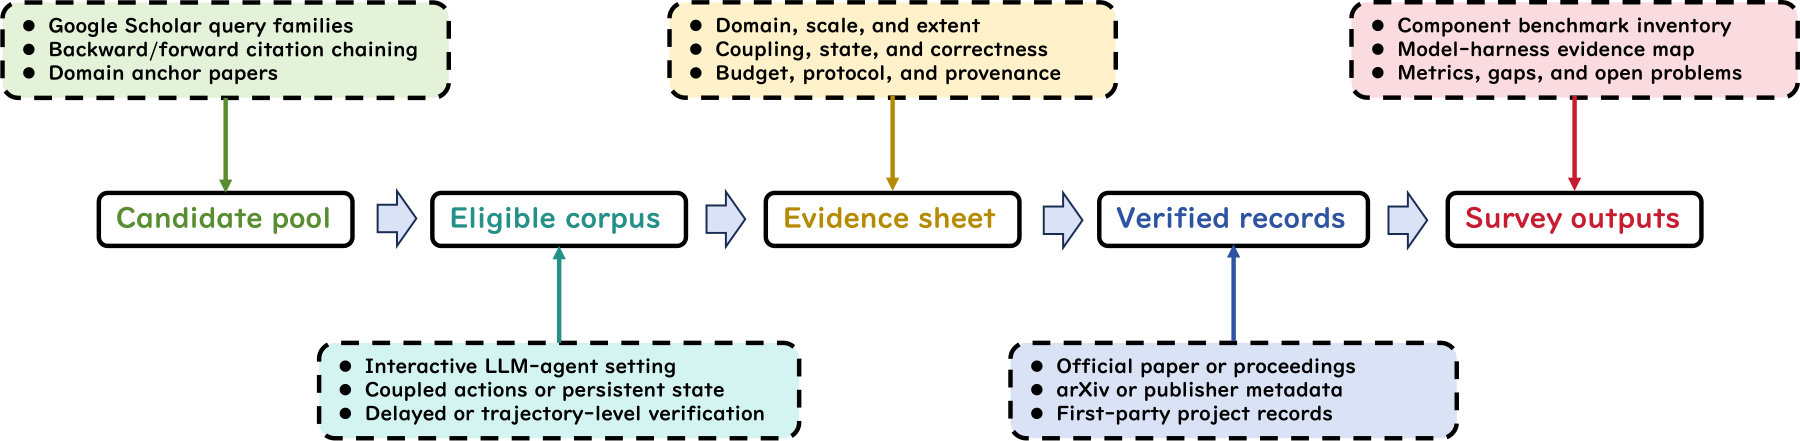
THE COMPANION SURVEY
AI4AI Survey
From Long-Horizon Agents to Recursive Self-Improvement—Definitions, Reliable Horizons, and Open Problems
A unified map of the systems, evidence, and design choices shaping AI that can help build better AI.
THE MAP KEEPS MOVING
Follow the frontier.
Updated weekly — until humanity achieves AI4AI. Star the repository, watch for weekly updates, and help shape what comes next.